Quick answer: why isn’t my brand showing up on Perplexity? If you rank on page one of Google but Perplexity never cites you, the cause is usually one of four things: (1) your firewall or
robots.txtblocksPerplexityBot, (2) your answers are buried in long paragraphs that are hard to quote, (3) few trusted third-party sites mention your brand, or (4) your pages look out of date. The five steps below fix each one.
It’s a frustrating spot to be in. Your key pages rank on Google, your domain is strong, and your keywords are well chosen. But when a buyer asks Perplexity for the best options in your category, your brand isn’t in the answer.
That gap between Google rankings and AI answers is what this guide is about. Answer engines like Perplexity don’t show ten blue links. They write a single answer and cite a handful of sources. If you’re not one of those sources, the buyer may never see you.
Fixing this is called Generative Engine Optimization (GEO), also known as Answer Engine Optimization (AEO). Traditional SEO gets a page ranked. GEO gets that page found, quoted and cited by AI search tools such as Perplexity, Google AI Overviews, ChatGPT search and Claude. Perplexity SEO is a good place to start, because Perplexity shows its sources so clearly.
There’s research behind this. In the 2024 KDD paper GEO: Generative Engine Optimization, researchers from Princeton, Georgia Tech, the Allen Institute for AI and IIT Delhi tested nine ways to rewrite web content. Adding citations, quotations and statistics raised a source’s visibility in AI answers by up to about 40%. Keyword stuffing was the only method that did worse than leaving the page alone.
Here’s how to get cited in Perplexity in five steps.
Traditional Google SEO vs. Perplexity GEO: Side-by-Side Comparison
Perplexity finds and uses pages differently from Google, so the priorities shift. Perplexity hasn’t published its ranking factors; the right-hand column reflects what practitioners commonly observe.
| Factor | Traditional Google SEO | Perplexity GEO |
|---|---|---|
| Goal | Rank high in the blue links and earn the click | Be one of the sources cited in the written answer |
| What seems to matter most | Backlinks, relevance and page experience | Quotable passages, third-party mentions and consistent facts about your brand |
| Best content format | Thorough, well-structured pages | Answer first, then tables, specific numbers and named sources |
| Freshness | Matters for some queries; evergreen pages can hold rankings for years | Recently updated pages often appear to be preferred |
| Crawler access | Googlebot | PerplexityBot in robots.txt, plus a firewall that lets it through |
| Main KPI | Rankings and organic click-through rate | Share of Model (SoM), citation frequency and AI referral traffic |
| Refresh cycle | Often yearly or twice a year | Every 60–90 days for your most important pages |
| Trust signals | Links from authoritative sites | Mentions on Reddit, review sites like G2 and Capterra, and industry lists |

Phase 1: Make Sure Perplexity Can Reach Your Site
No content fix matters if Perplexity’s crawler can’t load your pages. One rule in robots.txt or your firewall can hide an entire domain.
1. Are you blocking PerplexityBot in robots.txt or Cloudflare?
Start with yourdomain.com/robots.txt. Many sites block every bot except Google to save bandwidth or stop scrapers, and lock out answer engines by accident.
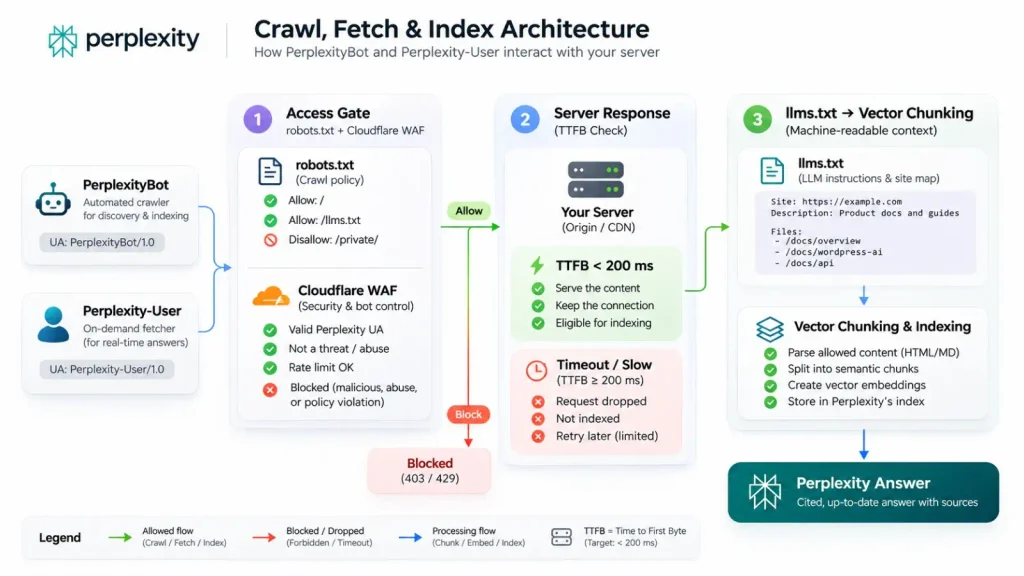
Perplexity uses two user agents, according to its crawler documentation:
PerplexityBotcrawls and indexes pages so they can appear and be linked in Perplexity’s answers. It followsrobots.txt. Perplexity says it isn’t used to train AI models.Perplexity-Userfetches a page live when someone’s question needs it. Because a person triggered the visit, Perplexity says it generally ignoresrobots.txt.
Add these lines to robots.txt. The last block lets in OAI-SearchBot, the crawler behind ChatGPT search, which most brands want too:
User-agent: PerplexityBot
Allow: /

User-agent: Perplexity-User
Allow: /

User-agent: OAI-SearchBot
Allow: /
Perplexity says robots.txt changes can take up to 24 hours to take effect.
Check your firewall too, especially on Cloudflare. Since 1 July 2025, new Cloudflare domains block known AI crawlers by default. And in August 2025, Cloudflare removed Perplexity from its verified bots list, so a “verified bots” allowance no longer covers it. In your Cloudflare dashboard, check the AI crawler settings and make sure
PerplexityBotisn’t blocked. Then follow Perplexity’s own advice: create a firewall allow rule that matches thePerplexityBotuser agent and an IP address from Perplexity’s published IP list. Matching both stops impostors from using the name. On Cloudflare’s free plan, Bot Fight Mode can’t be skipped with a custom rule, so you may need to switch it off.
2. Serve fast, server-rendered pages
Answer engines fetch pages while the user waits for an answer, so slow or empty pages are easy to skip.
- Keep server response time low. Perplexity doesn’t publish a timeout, but Google’s web.dev guidance treats a Time to First Byte of 0.8 seconds or less as good. Edge caching (Cloudflare, Fastly, or an NGINX FastCGI cache) helps a lot.
- Put your core text in the HTML. Many AI crawlers don’t run JavaScript the way Googlebot does. Make sure your main copy, pricing tables and FAQs are in the server-rendered HTML, not loaded later by a React or Vue bundle.
3. Add an llms.txt file (optional)
llms.txt is a proposed standard from Answer.AI’s Jeremy Howard: a short Markdown file at yourdomain.com/llms.txt that points AI tools to your most important pages. Think of it as a curated table of contents, where sitemap.xml is the full index.
Be realistic about it. No major AI search engine has confirmed it reads llms.txt when answering questions, and Google has said it doesn’t use it. It takes ten minutes to make, though, and it’s handy when people paste your site into an AI tool. Here’s a simple structure:
[Your Brand Name]
[One or two sentences on who you are, who you serve, and what you sell.]
Products & Pricing
- Product Features: Core capabilities and integrations.
- Pricing & Plans: Plan comparison for startups and enterprises.
Guides & Documentation
- API Documentation: Technical implementation guide.
- 2026 Industry Benchmark Report: Our original data and statistics.
Phase 2: Write Content That’s Easy to Quote
AI search tools don’t read your page top to bottom like a person. They pull out short passages that answer the question and cite the page those passages came from. If your answer is buried in the fourth paragraph, a competitor with a clearer page gets the citation.


1. How does the answer-first (BLUF) structure help citations?
BLUF means “Bottom Line Up Front,” a writing rule borrowed from military briefings. Open each H2 or H3 section with a short paragraph, roughly 40 to 60 words, that answers the heading’s question on its own.
Use names, not pronouns. Write “Acme CRM costs $49 per user” rather than “it costs $49 per user,” so the passage still makes sense when it’s lifted out of the page.
2. What did the Princeton GEO study find works best?
The researchers rewrote web pages nine different ways and measured how much of each AI answer came from the rewritten page. They tested on a benchmark of about 10,000 queries, then checked the results on Perplexity itself.
- Add statistics, quotations and citations. These three methods performed best, raising visibility by roughly 30–40% in the main tests. Swap vague claims (“our platform speeds up onboarding”) for specific ones (“customers cut onboarding from 14 days to 9 in Q1 2026”), then link to the source.
- Quote named experts. Quotation Addition was one of the strongest methods, and on Perplexity it improved visibility by about 22%.
- Don’t keyword-stuff. It was the only method that scored below the untouched baseline, both in the main tests and on Perplexity.
One more finding is good news for smaller brands: these edits helped lower-ranked pages far more than pages already ranked first.
3. Use question headings and real HTML tables
Phrase your H2s and H3s the way people ask questions, for example “How much does [Brand] cost for enterprise teams?” instead of just “Pricing.” Put comparisons, such as plans, specs or feature lists, in an HTML <table> instead of paragraphs. Tables keep each fact next to its label, which makes them easy to extract and quote accurately.
Phase 3: Build Trust Beyond Your Own Website
What you say about yourself only goes so far. For “best [category]” questions, answer engines lean on what other sites say, so a brand that’s only described on its own website often gets left out.

1. What is co-citation, and why does it matter for GEO?
Co-citation is when your brand is mentioned next to the established names in your category. Think of being listed alongside HubSpot, Salesforce and Pipedrive in an independent “10 Best CRM Platforms for 2026” article.
In classic SEO, an unlinked mention counted for little next to a backlink. For AI search, the mention itself is useful. Showing up in a dozen or so independent lists, comparisons and trade articles helps both search retrieval and future AI models connect your brand with your category.
2. Why Reddit, G2, Capterra and YouTube show up so often
Ask Perplexity a buying question about software or products, and you’ll often see Reddit threads, review sites like G2, Capterra and Trustpilot, and YouTube videos among the sources. Real user opinions are harder to fake than marketing copy.
- Reddit: Don’t drop links. Use an openly identified founder or engineer account and give detailed, honest answers in the subreddits your buyers read.
- Review sites: Keep a steady flow of new reviews on G2, Capterra or Trustpilot. Make sure your profile descriptions use the same words your buyers type into Perplexity.
3. Connect your profiles with sameAs schema
Help AI tools recognise that your website, LinkedIn page and review profiles are the same company. Add Organization JSON-LD to your homepage and About page, and list every official profile in the sameAs array. Only include a Wikidata link if your company already has an entry; Wikidata has its own notability rules.
{
  "@context": "https://schema.org",
  "@type": "Organization",
  "name": "Your Brand Name",
  "url": "https://yourdomain.com",
  "logo": "https://yourdomain.com/logo.png",
  "description": "One factual sentence on what your company does and its category.",
  "sameAs": [
    "https://www.wikidata.org/wiki/Q12345678",
    "https://www.linkedin.com/company/yourbrand",
    "https://www.crunchbase.com/organization/yourbrand",
    "https://www.g2.com/products/yourbrand/reviews",
    "https://github.com/yourbrand"
  ]
}
Phase 4: Keep Your Key Pages Fresh
Perplexity tends to cite pages that look current. A well-structured article updated last month often beats a “definitive guide” nobody has touched since 2024.
Why does freshness matter so much for AI answers?
Answer engines try not to repeat old prices, retired features or outdated rules. So they look for signs a page is current: the published and modified dates in your schema, the visible “last updated” date, and current-year references in the text.
The 60–90 day refresh schedule
Focus on the small set of pages that drive most of your pipeline: comparisons, pricing pages and your main category guides.
| Task | How often | Why it helps |
|---|---|---|
| Update statistics and benchmark data | Every 60 days | Replaces old figures with current ones worth citing |
| Refresh comparison tables and pricing | Every 60–90 days | Stops AI tools quoting stale prices from your page |
| Add 1–2 new questions and answers | Every 90 days | Covers new follow-up questions people are asking |
| Fix broken outbound links | Every 60 days | Keeps your citations trustworthy |
Update the visible “last updated” date and schema dateModified | With every real edit | Tells crawlers and readers the page is current |
| Submit changed URLs via IndexNow and resubmit your sitemap | Right after editing | IndexNow notifies Bing, Yandex, Naver, Seznam and Yep; Google relies on your sitemap and Search Console |
Don’t fake freshness. Changing the date without meaningfully changing the page misleads readers, and Google’s guidance warns against it. Update the date when you’ve actually updated the content.
Phase 5: Track Your Share of Model (SoM) and AI Traffic
Rank trackers only measure Google’s blue links. For GEO you need a different number: Share of Model (SoM), the percentage of your target AI questions where your brand is named or cited.

1. How to run a monthly “money prompt” audit
Write a list of 15 to 25 buying questions your customers actually ask, across the buying journey:
- Discovery: “What are the best [category] tools for [audience] in 2026-2027?”
- Comparison: “Compare [Competitor A], [Competitor B] and [Your Brand] for [use case].”
- Validation: “Is [Your Brand] worth it? What are the pros, cons and pricing?”
Once a month, run each one in Perplexity while logged out, so your history doesn’t shape the answer. Log three things: whether your brand is named in the answer, whether your site appears in the cited sources, and which third-party pages (a Reddit thread, a G2 listing) Perplexity drew on. Those third-party pages are your outreach list for Phase 3.
2. How to track Perplexity and AI referral traffic in GA4
When someone clicks a cited source in Perplexity, the visit usually shows up in GA4 as referral traffic. To group all AI answer engines in one report:
- Open GA4 > Explore and start a Blank exploration.
- Add Session source / medium and Landing page + query string as dimensions, and Sessions, Engaged sessions and Key events as metrics.
- Add a filter: Session source > matches regex, then paste:
.*(perplexity|chatgpt|openai|claude|copilot|gemini|you\.com).*AI traffic is usually smaller than its influence. Many people read the answer and never click, so treat SoM as your main metric and referral traffic as the backup.
3. Tools for automated GEO and Share of Model tracking
When spreadsheets stop scaling, dedicated GEO tools such as Profound, Peec AI, Otterly.AI, ZipTie.dev and Ahrefs Brand Radar run your prompts automatically across Perplexity, ChatGPT search and Google AI Overviews, and flag when a competitor replaces you in an answer.
Frequently Asked Questions (FAQ)
Why is my brand missing from Perplexity AI even though it ranks on Google?
Usually it’s one of four gaps. PerplexityBot is blocked by robots.txt or a firewall such as Cloudflare, answers are buried in long paragraphs instead of short answer-first passages and tables, few trusted third-party sites mention the brand, or key pages look out of date.
Which user agents does Perplexity use to crawl websites?
Two. PerplexityBot crawls and indexes pages for Perplexity’s search results and follows robots.txt. Perplexity-User fetches pages live when a user’s question needs them, and Perplexity says it generally ignores robots.txt. Allow PerplexityBot in robots.txt and let Perplexity’s published IP addresses through your firewall.
How long does it take for changes to show up in Perplexity?
Perplexity says robots.txt changes can take up to 24 hours to take effect. There’s no published timeline for content changes. They show up once Perplexity recrawls the page or fetches it live for a question, so recheck your money prompts after a week or two.
Does domain authority still matter for Perplexity SEO?
Indirectly. Perplexity doesn’t use Google’s PageRank and hasn’t published its ranking factors. But pages that rank well in traditional search and are widely mentioned on trusted sites tend to be cited more often.
Does llms.txt guarantee that Perplexity will cite my website?
No. No major AI search engine has confirmed it reads llms.txt when answering questions. Crawler access, fast server-rendered pages and clear, well-sourced content matter far more.
How can I track Perplexity traffic in Google Analytics 4 (GA4)?
Build a GA4 exploration with Session source as a dimension and filter it with a regex that matches AI sources such as perplexity, chatgpt, claude, copilot and gemini. Clicks on Perplexity’s cited sources usually appear as referral traffic from perplexity.ai.